Vector-based internal linking: connections keywords can’t see
How to use embeddings and cosine similarity to find semantic internal linking opportunities at scale. Concept, practice and tools.
highlights
- Two articles can cover the same subject without sharing a single keyword. The lexical model doesn’t connect them. The vector model does.
- Vector-based linking starts from the meaning of pages, not their words. The result is link suggestions a manual process would rarely find.
- The similarity threshold is the main decision in the process: too low and suggestions become irrelevant, too high and you miss real connections.
- Automation discovers the opportunities. Deciding where and how to insert the link is still editorial.
- For large sites, the analysis scales with tools like Screaming Frog v22.0 or Python with sentence-transformers, without complex infrastructure.
the problem with the lexical model for internal linking
How internal linking is done on most sites today: a manual list of opportunities, plugins that cross-reference tags and categories, searches for pages that mention a given keyword. All of these methods start from words.
Screaming Frog documented the problem well: when you map pages by similarity of meaning, connections emerge that a manual process simply wouldn’t find. Not because anyone was negligent, but because it’s humanly impossible to keep in your head every possible semantic relationship among hundreds of articles published over the years.
A site with 500 articles and a manual linking process probably has dozens of strong connections that were never made because each article uses different vocabulary. Those connections don’t exist, and the topical authority that could flow between pages stays trapped.
how vector-based linking works in practice
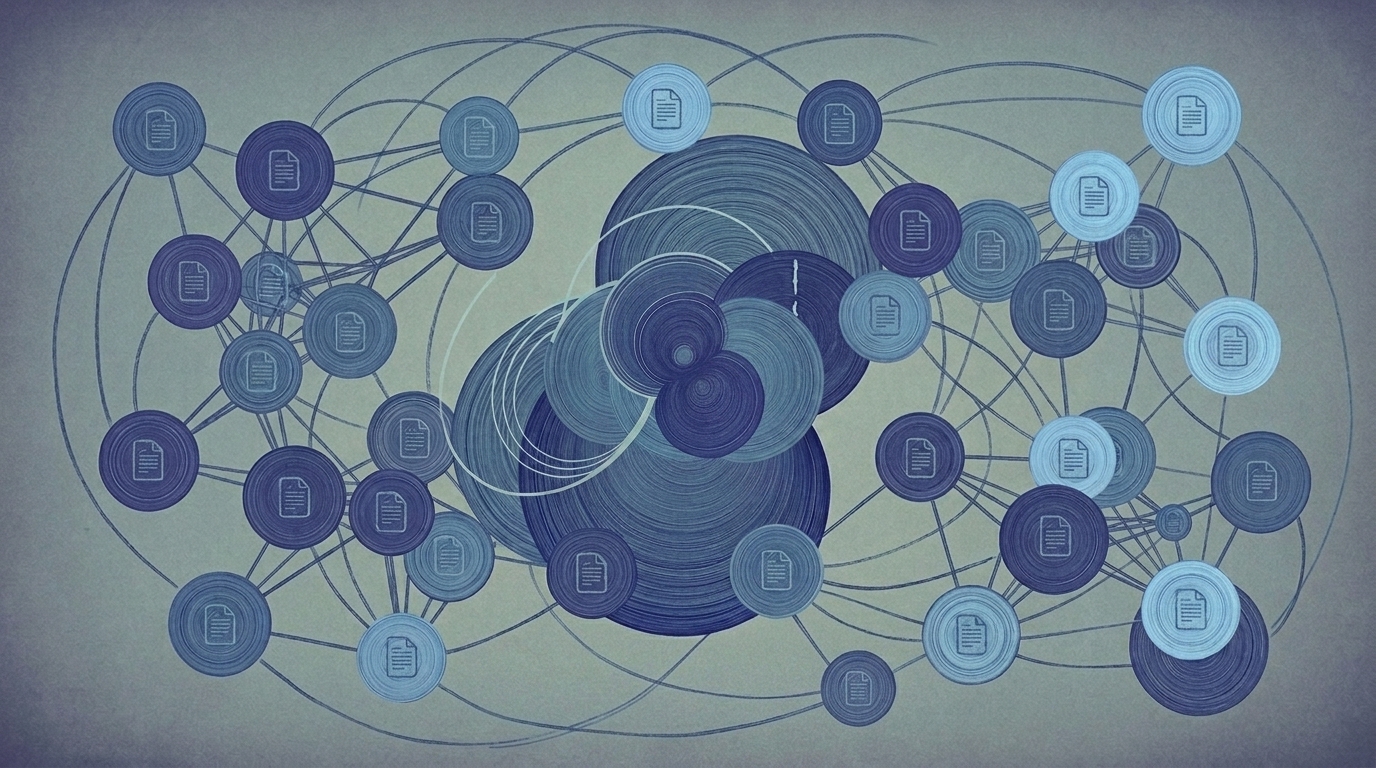
The workflow has four steps. Crawl the pages to capture the clean content of each URL. Generate one meaning vector per page. Calculate how close those vectors are to each other, pair by pair. Filter the most relevant suggestions by a minimum similarity score.
That minimum score, called the threshold, is the most important decision in the process. A value of 0.7 or higher tends to capture a real semantic relationship between pages. Below that, the model starts suggesting loose connections that don’t justify a link. The right number varies: a site specialized in a single topic will have higher average scores than a general-interest portal, so the threshold needs to be calibrated for each context.
Screaming Frog v22.0 introduced native semantic search: you describe what you’re looking for and it returns the crawled pages closest in meaning. That’s exactly this logic applied to link discovery, without writing a single line of code.
On anchor text: when you know two pages are semantically close, the ideal anchor doesn’t need to be the target page’s exact keyword. It can be the concept that appears naturally in the source paragraph. The result is organic anchor text variation, without forcing it.
semantic mesh: links that emerge from the content
The traditional internal linking model is hierarchical: you define a main page (the pillar), secondary pages around it (the spokes), and the spokes link to the pillar. The structure is decided before any content analysis.
The Semantic Mesh concept flips that logic: the link network emerges from the content itself. Any pair of pages with high similarity becomes a link candidate. This reveals connections between different clusters that the hierarchical model wouldn’t capture: a technical SEO article may have high semantic affinity with a content production article, and that connection makes editorial sense even though it sits outside the planned hierarchy.
Our hypothesis is that this model distributes topical authority in a way that more faithfully reflects what search systems see as contextual relevance. There’s no public data that proves this directly, but it’s structurally consistent with how semantic retrieval works.
A word of caution: full automation, with links published without review, requires care. The risk is repetitive anchor text and too many links coming out of the same page. The real value of the process lies in assisted discovery: the model suggests, the analyst decides.
what the model doesn’t solve
A high similarity score doesn’t guarantee the link will work anywhere in the article. Two pages can be semantically close, but the context of a specific paragraph may not justify the link at that point.
The model finds the candidates. Deciding where to insert the link, with which anchor and how often, remains editorial. That’s not a limitation of the process; it’s the right division of labor between automated analysis and human judgment.
For very large sites, comparing every page with every other page can get slow. But for most content sites, the process runs without issues using the tools below.
where to start
Screaming Frog v22.0 with the OpenAI or Ollama integration (free, local) is the most direct path: crawl, embeddings and semantic search in a single tool, with no additional setup.
If you want more control over the process, Python with sentence-transformers handles the full workflow for sites of up to a few thousand pages. You generate the embeddings, calculate the scores and export the pairs above the threshold for review.
final thoughts
Vector-based internal linking doesn’t replace editorial judgment. It replaces the reliance on word matching to discover which pages deserve to be connected.
On sites with a lot of content, the manual process is incomplete by definition: nobody can track every semantic connection among articles published over the years. Vectors do that mapping. What to do with it is still up to whoever knows the site.
Lucas Cassapula
Partner & Head of SEO at Wesearch and Co-founder of Mentionflow
I am a partner at Wesearch and co-founder of Mentionflow. I have worked with SEO for almost 10 years. I am a data-driven geek who is always testing hypotheses, looking for patterns and turning ideas into products. I share studies, experiments and automations focused on SEO and GEO.