How vector clustering reveals the architecture algorithms see on your site
How to use embedding clustering to map your site’s real semantic architecture, identify editorial gaps and make better-grounded content decisions.
highlights
- The category structure your editorial team defined doesn’t always match the groupings algorithms see. The two coexist, but the gap between them is actionable.
- Vector clustering groups pages by similarity of meaning, not by folder hierarchy or manual category.
- The output reveals misplaced content, clusters without a clear central page and topics covered in a fragmented way that could be consolidated.
- Site Focus Score is a reading derived from clustering: it measures how far each page drifts from the site’s thematic center.
- This isn’t a one-time analysis. As the site grows, the semantic map changes.
what vector clustering actually does
The technique starts from the same workflow as the other articles in this series: crawl the pages, generate one embedding per URL, calculate similarity between pairs. The difference is what you do with that data.
Instead of comparing isolated pairs, clustering groups every page into sets based on semantic proximity. Algorithms such as K-Means or HDBSCAN do this grouping automatically: you define (or let the algorithm infer) how many clusters you want, and each page is assigned to the group whose centroid is closest to its embedding.
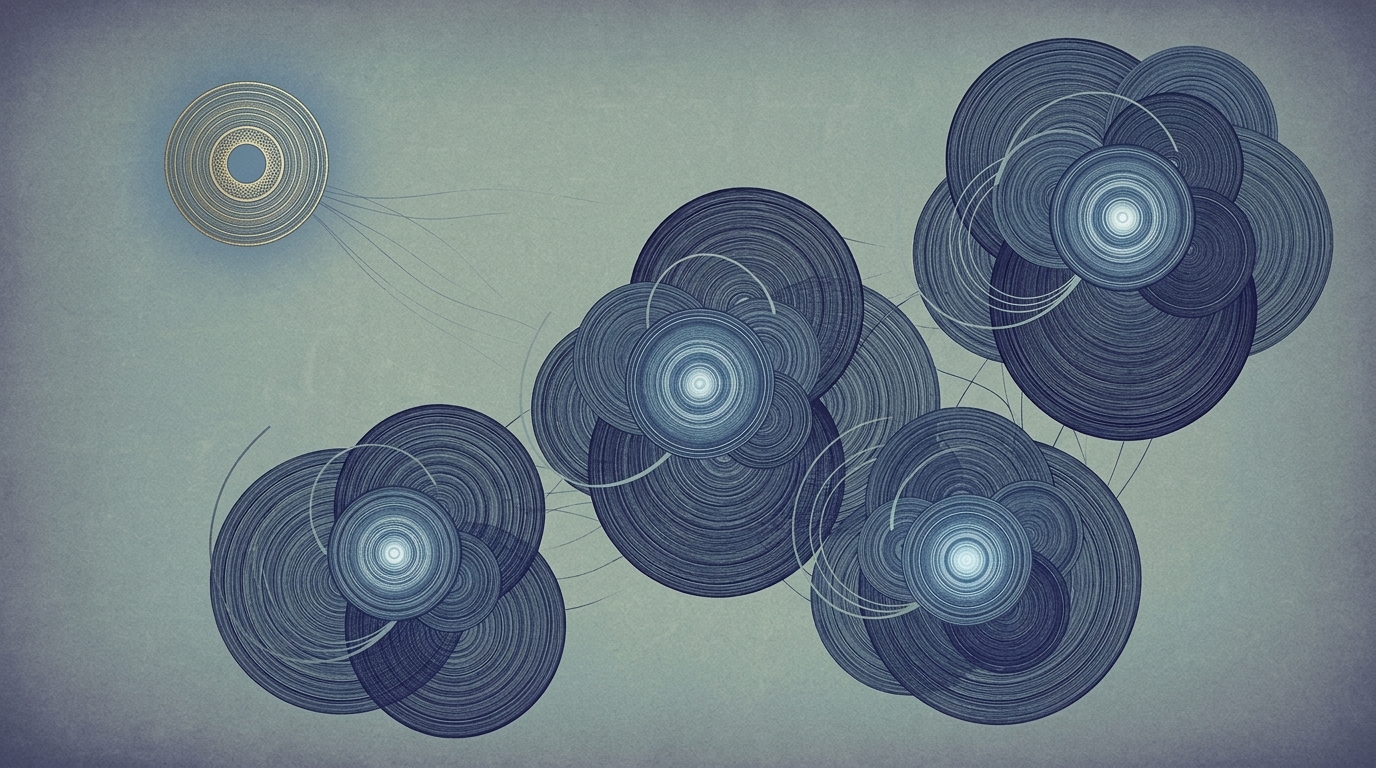
The result is a map. Each cluster represents a real thematic territory on the site. Pages within the same cluster are semantically close. Pages in different clusters deal with distinct subjects.
Screaming Frog v22.0 implements this concept with its “most representative page” feature: the page in each cluster whose vector position is closest to the group’s centroid.
what the map reveals in practice
Four patterns show up frequently the first time you run this analysis on a site with a reasonable volume of content.
Pages outside their expected cluster
An article published under the "Technical SEO" category that the algorithm assigns to the "content production" cluster. It isn’t necessarily a mistake, but it’s a sign that editorial positioning and semantic positioning don’t match.
Clusters without a central page
A group of semantically close pages where none of them stands out, whether by authority, depth of coverage or traffic. It’s an opportunity to create or strengthen a pillar page for that territory.
Fragmentation where there should be consolidation
Three or four pages in the same cluster with very high similarity scores between them. Consolidating them into one more complete page tends to be more effective than trying to differentiate pages the algorithm already treats as nearly identical.
Isolated clusters
Pages that form a small cluster or stand alone, with no strong semantic connection to the rest of the site. They may indicate content outside the domain’s thematic scope, which has implications for the Site Focus Score.
site focus score — the domain’s thematic coherence
The site centroid is the vector average of all pages. It’s the point that semantically represents the domain’s core subject. Each page has a distance from that centroid, which Screaming Frog calls drift.
Site Focus Score is a reading derived from that average distance: the lower the pages’ average drift from the centroid, the more thematically cohesive the site. A specialized blog has a high score. A portal that publishes about everything has a low score.
The 2024 Google documentation leak sparked inferences about an internal site focus concept that would influence rankings. There is no conclusive documentation on this, and it’s important to treat it as a hypothesis.
In practice, pages with high drift deserve attention. Not necessarily removal, but evaluation: does that page belong on this domain? Is it contributing to topical authority or diluting the site’s cohesion?
how to use clusters for editorial decisions
Cluster analysis doesn’t produce a list of direct tasks. It produces a map that informs decisions that still depend on editorial judgment.
For content planning: clusters with many pages but no in-depth coverage are candidates for a new pillar page. Small clusters with high traffic point to valuable territory that hasn’t been fully explored yet.
For consolidation: pages in the same cluster with scores above 0.85 and low traffic on both are natural merge candidates. The resulting page usually performs better than the two separately.
For linking architecture: the cluster map is the most solid foundation for defining internal linking. Pages in the same cluster have more semantic reason to link to each other than pages in different clusters.
how often to run this analysis
Once isn’t enough. A site’s semantic map changes as new content is published, pages are updated and the editorial focus evolves.
The cadence depends on publishing volume. Sites that publish regularly benefit from a quarterly analysis. For more static sites, twice a year is enough to capture relevant drift.
Screaming Frog with its embeddings integration is the most direct path. If you already have Python in your workflow, sentence-transformers with HDBSCAN handles clustering at a more granular level.
final thoughts
The content architecture that exists in the spreadsheet and the semantic architecture algorithms see aren’t always the same thing. This isn’t a problem to solve once and for all; it’s a permanent tension that needs to be monitored.
Vector clustering is the tool that makes that tension visible. What to do with what shows up on the map is still editorial work: deciding what to consolidate, what to strengthen, what to reposition and what to simply accept as it is.
Lucas Cassapula
Partner & Head of SEO at Wesearch and Co-founder of Mentionflow
I am a partner at Wesearch and co-founder of Mentionflow. I have worked with SEO for almost 10 years. I am a data-driven geek who is always testing hypotheses, looking for patterns and turning ideas into products. I share studies, experiments and automations focused on SEO and GEO.